Meet OceanBase AI Lakebase, the unified database for operational data, real-time analytics, and AI.
Meet OceanBase AI Lakebase, the unified database for operational data, real-time analytics, and AI. Explore ->
Breaking 90% on DAB: What It Takes to Build a Reliable Data Agent
- OceanBase's Data Agent reached 90.62% on the Data Agent Benchmark (DAB) from UC Berkeley's EPIC Data Lab and Hasura PromptQL, becoming the first submission to cross the 90% mark.
- It ran on the open-source GLM-5.2 as its base model and still outscored solutions built on frontier proprietary models like GPT and Claude. On DAB, accuracy comes from the whole model + agent + data-system stack, and the base LLM is only one part of it.
- DAB measures whether an agent can find the correct answer inside messy, real-world data: comprehension, selection, planning, computation, and result verification. That is a different problem from Text-to-SQL.
The question isn't "can AI write SQL" anymore
Text-to-SQL benchmarks answer a narrow question: given a schema and a plain-English request, can the model emit valid SQL? That was the right question in 2023. It isn't the interesting one now.
Put an agent in front of a real analytical environment, with dozens of tables across PostgreSQL, MongoDB, and DuckDB, ambiguous column names, metrics defined three different ways, and relationships nobody documented. Generating syntactically correct SQL is table stakes. The hard part is everything around it: figuring out which data answers the question, planning a multi-step analysis, running it, and knowing whether the answer is actually right.
That gap between "the model can write a query" and "the system returned the correct answer" is exactly what the Data Agent Benchmark was built to measure.
What DAB actually tests
The Data Agent Benchmark (DAB), released by UC Berkeley's EPIC Data Lab in collaboration with Hasura PromptQL, evaluates data agents across domains that look like real workloads: consumer internet and local services, finance and equities, biomedical, intellectual property, enterprise operations, software engineering and media. Tasks span multiple database engines, including PostgreSQL, MongoDB, SQLite, and DuckDB, rather than a single clean schema.
The distinction from Text-to-SQL matters:
| Text-to-SQL | Data Agent Benchmark (DAB) | |
| Core question | Can the model translate NL → SQL? | Can the agent find the correct answer in a real data environment? |
| Input | A question, schema, and supporting context | Complex, scattered, heterogeneous data |
| What's tested | Query generation and result correctness | Data comprehension → selection → planning → computation → verification |
| What "success" means | The query produces the intended result under the evaluation protocol | The final answer is correct and defensible |
In other words, solving DAB tasks involves the full journey from understanding data to arriving at an answer. A single task requires the agent to comprehend the data, pick the right sources, plan an analysis path, execute the queries and computation, and then validate the result.
That makes DAB a test of a whole system rather than a model. An LLM handles comprehension and reasoning; an agent handles planning and execution; and the data layer has to support discovery, cross-source joins, and result validation. If those three don't cooperate, the agent produces confident, wrong answers.
The result: 90.62%, and what's underneath it
OceanBase's Data Agent reached 90.62% accuracy on DAB and became the first submission to break 90%. (Internally the submission carried the codename Scout; the capabilities behind it are being consolidated into OceanBase DataPilot.)
The headline number is notable, but the detail underneath it is more instructive.
OceanBase built the solution on the open-source GLM-5.2 as its base model, and it still finished ahead of solutions built on frontier proprietary models, including GPT- and Claude-based agents. If raw model horsepower were the deciding factor, an open-weights base model shouldn't come out on top.
It happened because on a benchmark like DAB, the base model is only one part of the system. Once a model reasons well enough, accuracy comes down to everything the data system does around it: whether the agent understands the schema well enough to pick the right tables, whether it can plan a correct multi-step path, and, most important, whether it can catch its own mistakes before returning an answer. DAB rewards the combined capability of model, agent, and data system, and the data system is where OceanBase's design earns its score.
Inside the data agent: a verify-and-repair loop
The reason one-shot NL2SQL plateaus is that it has no way to recover from a wrong turn. OceanBase's Data Agent is built as a loop instead: understand, plan and execute, then verify and repair.
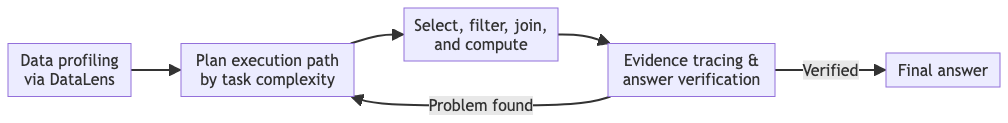
- Understand the data.
The system uses a component called DataLens to build a profile of the environment, identifying fields, their likely roles, and candidate relationships between them. This gives the agent additional context for interpreting ambiguous schemas.
The profile draws on schemas, row counts, column statistics, and bounded samples. These signals help identify candidate keys, time fields, measures, text fields, and possible relationships. Profiles retain information about where those signals came from, while the semantic catalog organizes them into a form usable by planning and execution.
Relationship discovery goes beyond matching column names. Candidate joins can be probed against source values, and measured key overlap is distinguished from an unverified suggestion. This matters when equivalent identifiers use different formats or when a field contains a serialized list. A sample match provides evidence for a candidate relationship; execution still needs to check how that relationship behaves on the selected data.
When required information is embedded in text, extraction and classification tools can turn it into structured records for downstream computation. The system tracks record identities and coverage to help identify when a bounded sample or incomplete extraction does not cover the required analytical population.
2. Plan the path.
Based on the complexity of the task, the solution plans an execution path rather than firing a single query. Simple lookups stay simple; multi-step questions get a multi-step plan covering data selection, filtering, joins, and computation.
The choice of execution path also considers the operations the question requires and the relationships the available evidence can support, with additional planning invoked when needed.
The current implementation represents task requirements in an operation graph and explicit answer and metric contracts. These structures can capture source roles, field bindings, filtering scope, aggregation grain, time roles, and output requirements. For example, a percentage needs both a numerator and a denominator population; a ranking needs a defined comparison set and ordering rule.
Workflows are compiled into data-kernel operations and validated before dispatch. For cross-database analysis, the system issues source-specific queries and combines intermediate results in a workflow. During joins, it can inspect key uniqueness, observed cardinality, and changes in row counts. These checks help identify unintended row multiplication before it distorts an aggregate.
3. Verify and repair.
After producing a result, the system runs evidence tracing and answer verification, checking both the computation process and the output. When it detects a problem, it can gather additional evidence, correct the computation, or revise the affected workflow and re-verify. Final answer selection considers the available execution evidence, the answer requirements, and unresolved blocking issues.
The system maintains an evidence ledger that links results to the tools and computations that produced them. Evidence carries identifiers and revisions, allowing the runtime to distinguish an active result from one superseded by a later computation. Structured answer products connect returned values to information about their fields, population coverage, filtering conditions, aggregation grain, and selection rules.
Relevant checks depend on the task and execution path. They can include query re-execution, aggregation and output-completeness checks, and targeted checks of joins, time filters, and ranking boundaries. The aim is to catch errors such as computing from a partial population, using the wrong counting unit, omitting requested fields, or returning values that conflict with the selected computation.
Repair is bounded. After a computation or workflow is revised, the agent runs the relevant checks again; internal verification is not a general guarantee of correctness.
This "understand, plan and execute, verify and repair" loop is the structural reason the solution stays accurate where single-pass approaches drift. Verification helps distinguish supported results from plausible but unsupported answers. This design also makes intermediate decisions inspectable and gives the agent concrete feedback for correction.
Why this matters beyond a leaderboard
For most of their history, databases had one job with respect to analytics: store data, run queries, return rows. The application, or the human, supplied the understanding.
AI agents change the contract. An agent doesn't just want rows; it needs to understand what the data means, relate it across sources, analyze it, and confirm the result is trustworthy. The center of gravity shifts from "hand the data to the AI" to "help the AI actually put the data to work."
That shift is the direction OceanBase is building toward: from a distributed SQL database into an AI data platform. The capabilities validated on DAB, including data comprehension, task planning, analytical execution, and result verification, are being consolidated into OceanBase DataPilot, the product line aimed at AI-driven data analysis. The goal is to move agents from calling data to completing tasks with data.
Seen that way, the DAB result points to a broader change in what a database is for. The database is becoming more than the data foundation underneath AI. It is turning into the engine that helps AI reason over data correctly.
Try it
If you're building analytical agents and hitting the same wall, where models write fluent SQL but still return confidently wrong answers, the data system is usually the lever that moves accuracy. To see how OceanBase approaches data comprehension, planning, and answer verification, explore OceanBase DataPilot and the DataPilot deep dives on the OceanBase blog.
Benchmark figures reference the Data Agent Benchmark (DAB) leaderboard from UC Berkeley's EPIC Data Lab and Hasura PromptQL. Verify the current standings against the official leaderboard before citing.


Keep Reading
View all posts
I Built a Knowledge Base That Thinks — Inspired by Karpathy's LLM Wiki
Inspired by Karpathy's LLM Wiki, ex-brain is an open-source personal knowledge base that compiles, links, and evolves your notes using LLMs and seekdb's hybrid search.

From Complex to Simple: How We Built seekdb for the AI Era
AI era doesn't need another heavy, complex enterprise database. It needs agility. It needs flexibility. We went back to the drawing board to understand what an AI application actually needs from a database. Our answer is OceanBase seekdb
Stop Letting Agents Write Directly to Production: Git-Like Version Control for Your Data
seekdb 1.2.0 adds Fork Database, DIFF TABLE, and MERGE TABLE — Git-like branching, diffing, and merging for your data, built into the database engine.